published · IEEE Trans. Affective Computing
Sound Emotion Model
Predicting how sounds feel, beyond happy or sad, from 4,000+ audio files. A LightGBM model beat the deep learning baselines by about 11% while training about 85% faster.
research team · with Christopher Anderson, Miles Thorogood (UBC), Etienne Richan + Louis-Xavier Buffoni (Audiokinetic)
Sound Emotion Model
- who
- research team · with Christopher Anderson, Miles Thorogood (UBC), Etienne Richan + Louis-Xavier Buffoni (Audiokinetic)
- why
- Sound is a big part of how games, films and VR make you feel. But the tools sound designers use to search for and recommend sounds mostly know a few simple labels and low-level signal features, not how a listener actually hears a sound. Could a model predict those richer feelings straight from the audio?
- what i did
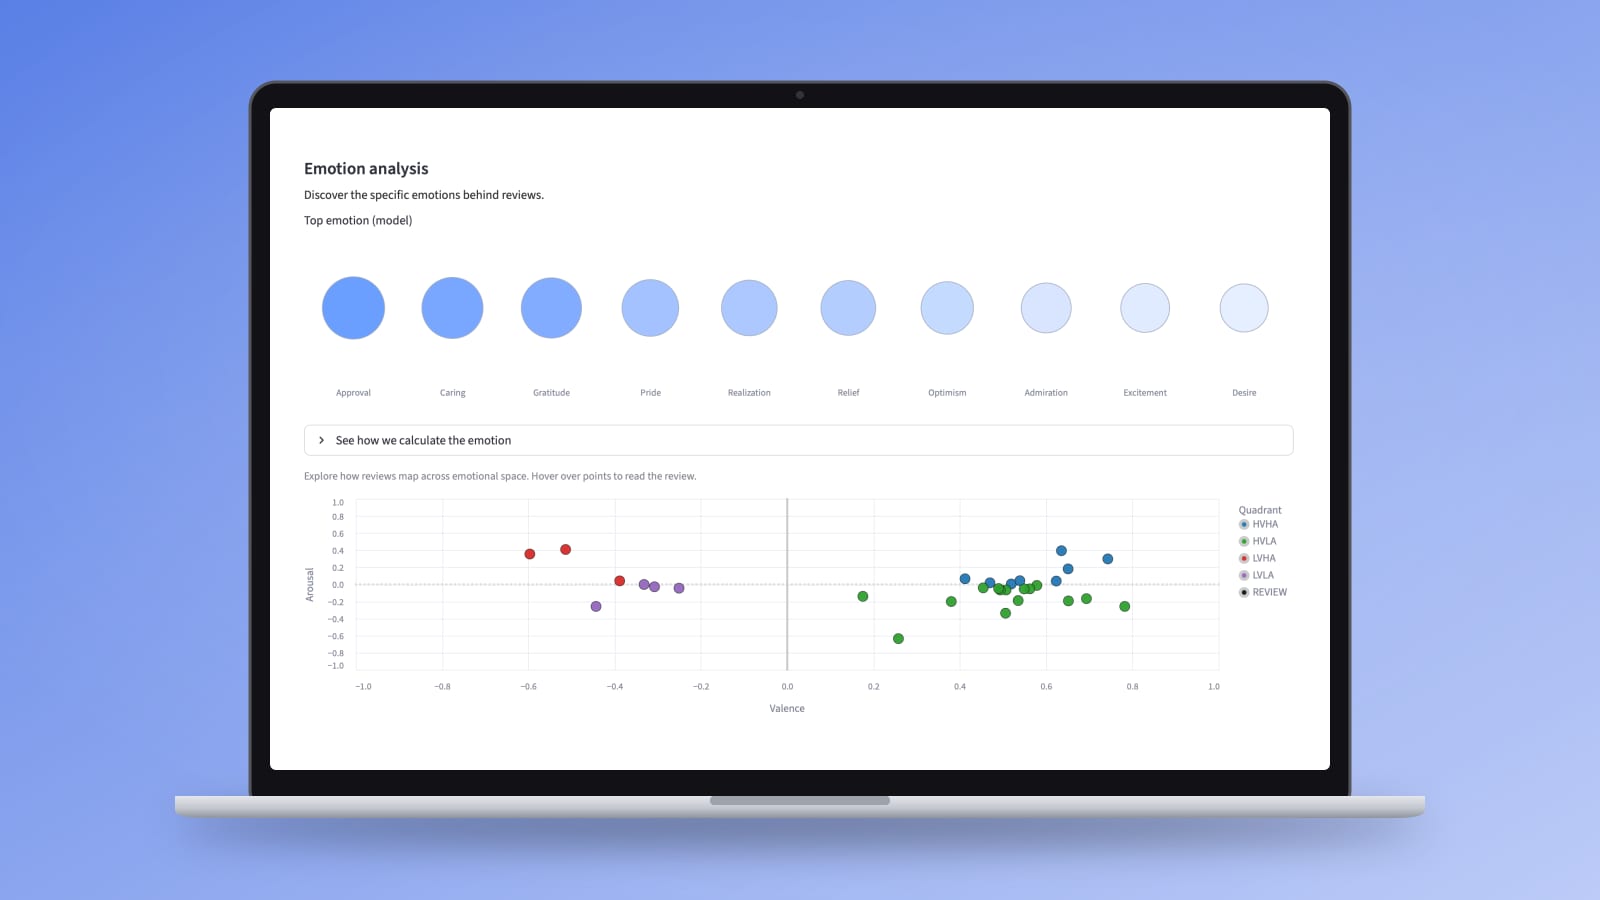
- I built Python pipelines to clean and analyse 4,000+ audio files with their acoustic features and labels for high-level sound descriptors. Then I trained and tuned models with LightGBM and Optuna, used feature selection and PCA, and made the figures that explain the results.
- what happened
- About 11% more accurate than the deep learning baselines while training about 85% faster. Published in IEEE Transactions on Affective Computing (early access) as “An Efficient Method for Predicting High Level Sound Descriptors by Mapping Audio Signals Within an Enriched Valence and Arousal Model”, with me as first author.
- ML research
- Python · LightGBM · Optuna · scikit-learn · SPIRAL × Audiokinetic · 2024–26
- published · IEEE Trans. Affective Computing
- read the paper ↗